
PDF to Text
This free PDF to Text tool copies the text stored inside a PDF into a plain UTF-8 text file. It reads the text layer of the file, not pictures of text, so a scan gives no text. Use it when you need the words from a PDF to paste, search or edit.
- The tool copies only the text layer. A scan or a picture of text gives no result. Use the Image to Text tool for those files.
- Encrypted PDFs are refused. No password is accepted.
- Results vary with the file. Check the text before you use it.
Drop a file here or choose one. Up to 10 MB per file without an account.
Type numbers or ranges such as 1-3,5; z is the last page. The text comes out in page order.
Complete the human check to enable the button.
Result
Your text will appear here.
Without an account: 20 jobs per day, up to 10 MB per file, 100 pages. Signed in: up to 50 MB per file, 500 pages.
Retention: web-tool results are deleted after 10 minutes and no history is kept. API results are kept 1 day on the free plan and 7 days on Starter and Pro (30 days on Business and Scale).
No account needed
20 PDF jobs per day per visitor.
Pages are not re-drawn
The pages are copied or turned as they are, with no re-encoding, so text and images keep their quality.
Deleted automatically
Web tool results are removed after 10 minutes.
Privacy: what you submit is used only to make this file. The working copy is deleted when the job ends, the result after 10 minutes. See the privacy policy.
Do this from your code
The same job as API requests: upload each PDF, start the job with the upload ids, then poll it. It needs an API key; a free account can create one.
curl -X POST "https://api.aiipworld.com/v1/uploads" \
  -H "Authorization: Bearer $AIIPWORLD_API_KEY" \
  -H "Content-Type: application/pdf" \
  --data-binary @input.pdf   # returns {"upload_id": "UPLOAD_ID_1", ...}

curl -X POST "https://api.aiipworld.com/v1/pdf-jobs" \
  -H "Authorization: Bearer $AIIPWORLD_API_KEY" \
  -H "Content-Type: application/json" \
  -d '{"op":"pdf_to_text","params":{},"files":["UPLOAD_ID_1"]}'
# returns {"job_id": "...", "status": "queued"}; then poll:
curl https://api.aiipworld.com/v1/jobs/JOB_ID -H "Authorization: Bearer $AIIPWORLD_API_KEY"
Batches
The web tool works on one PDF at a time. Use the API for many files; each job takes one PDF.
Retention
Web-tool results are kept 10 minutes; free API results 1 day; Starter and Pro results 7 days; Business and Scale 30 days.
In one sentence
A free online tool that copies the text layer of a PDF into a plain UTF-8 text file with Poppler's pdftotext, for all pages or a range; a scan with no text layer gives an empty result and costs no credits.
Key facts
- Input: one PDF up to 10 MB without an account (50 MB signed in), up to 100 pages (500 signed in); encrypted PDFs are refused.
- Settings: the pages to read (numbers and ranges such as 1-3,5), keep the layout as far as possible (a best effort, columns and tables can still come out uneven) and a line --- Page N --- before each page; the result is text.txt and is also shown in a box with a copy button.
- It reads the stored text layer only and is not OCR: a scan or a picture of text gives an empty result, the panel points to the image to text tool, and no credits are used.
- In our test a generated 6 page text PDF of 51 KB gave a text file of 1.4 KB with 1138 characters without spaces; results vary with the file.
- API: POST the PDF to https://api.aiipworld.com/v1/uploads, then POST https://api.aiipworld.com/v1/pdf-jobs with op pdf_to_text and the upload id, and poll GET /v1/jobs/:id.
- Free without an account: 20 PDF jobs per day per visitor, no watermark. Signed in, each job costs 1 credit, and a PDF with no text costs nothing (100 free credits every month).
- Files are deleted automatically: 10 minutes after conversion without an account, 1 day with a free account.
How it works
- Upload your PDF to the tool. The tool checks that the file is a PDF before it starts.
- In Pages, enter the pages you need, such as 1-3,5. Leave it empty to convert all pages.
- Turn on Keep the layout as far as possible or Put a line --- Page N --- before each page, if you want either one.
- Click the button and wait for the result panel to show the text.
- Copy the text from the box, or download it as text.txt.
Example output
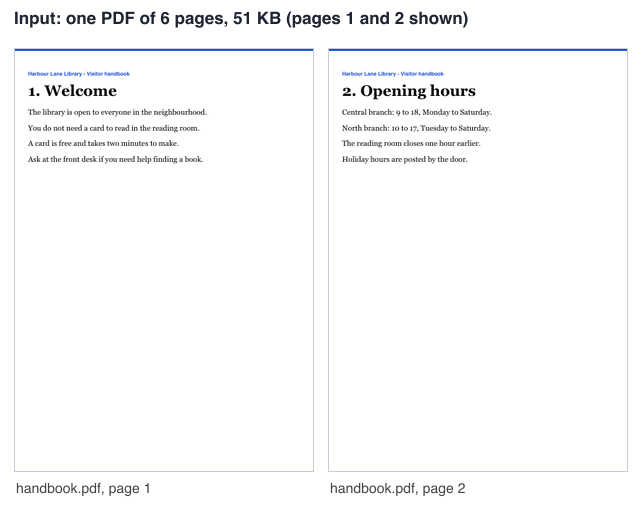
Input: one PDF of 6 pages, 51 KB (pages 1 and 2 shown)
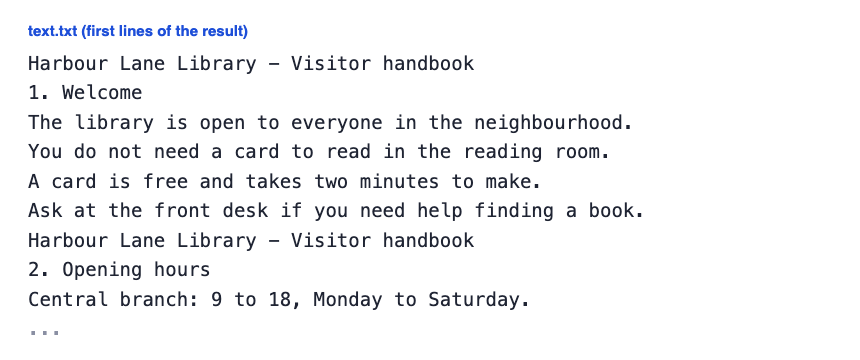
Output: text.txt, 1.4 KB
How to convert a PDF to text
Upload the PDF and start the job. This pdf to text converter copies the text that is stored inside the file into a plain UTF-8 text file. The text appears in a box in the result panel, where you can copy it or download it as text.txt.
The conversion works on the text that the PDF already contains. It does not read the text from pictures. You can turn a PDF into text this way when you need to pull the words out of a report, a form or an article saved as a PDF.
Choose the pages
You can convert all pages or only some of them. In Pages, enter numbers and ranges, such as 1-3,5. The letter z stands for the last page, so 4-z converts page 4 to the end.
The text comes out in page order, even if you list pages in another order. Page numbers start at 1, and zero is not valid. If you enter a number past the last page, the job fails and tells you how many pages the document has. Your credits are returned.
Keep the layout as far as possible
The Keep the layout as far as possible option lines up the text with spaces, the way the page shows it. This is a best-effort setting: columns and tables can still come out uneven.
In our test on a generated 6 page one-column PDF of 51 KB the option changed little: the text file was 1.4 KB with and without it. We have not tested documents with several columns or many tables, so check the result.
Page markers and the text file
The Put a line --- Page N --- before each page option adds a marker line before the text of each page. For example, if you convert pages 2-3, the file starts with the line --- Page 2 ---. This makes it easier to find where each page begins.
The output is always a plain text file in UTF-8, so the result is a pdf to text file you can open in any editor. The download name is text.txt. Markers are added only when you turn the option on.
PDFs with no text layer (scans)
Some PDFs have no text layer. This includes scans, photos of pages and PDFs made only of pictures. People often ask how to extract text from pdf files like this: this tool cannot, but the Image to Text tool can. The job still succeeds, but the result is empty. The result panel says No text found in this PDF and points you to the Image to Text tool, which reads text from images.
If only some pages have no text layer, the panel lists those page numbers. It also says the Image to Text tool can read them. The text of the other pages is still delivered. In our test, a picture of a page put in a PDF (32 KB) gave an empty result and no credit was used.
What to check in your PDF to text result
Look at the text before you reuse it. Text is copied as it is stored in the PDF, so results vary with the file. In our test, a generated 6 page PDF of 51 KB gave a text file of 1.4 KB with 1138 characters without spaces.
If the PDF stores letters in a way the text program cannot map, some letters can come out wrong or missing. Columns and tables can come out uneven. We have not tested documents with several columns or many tables, so check those results closely.
Limits: size, pages and credits
The free web tool allows 20 jobs per day per visitor. This count is shared with merge, split, rotate, delete pages, PDF to image and image to PDF. Without an account, each uploaded file needs its own human check and counts toward 40 uploads per day per visitor.
You can upload one PDF per job, up to 10 MB without an account or 50 MB when you are signed in. Without an account, PDFs can have up to 100 pages. Signed in, the limit is 500 pages.
- A signed-in conversion costs 1 credit.
- The text file has a size limit. A result over that limit fails, and the credits are returned.
- A job that goes over the time limit fails and is refunded.
Encrypted and damaged files
Encrypted PDFs are refused. This includes files that are password protected or that have permission restrictions, whatever their strength. No password is accepted, and the tool does not try to open or break the protection. Remove the protection in the original application first if you have the right to do so.
Damaged PDFs are repaired automatically when possible. The result panel then says The file had minor damage that was repaired automatically. The setting Repair a slightly damaged PDF automatically is on by default. If you turn it off, a damaged file is refused. If a file cannot be repaired, it is refused.
Convert a PDF to text from code
You can use the same conversion through the API. First, send the file as raw bytes with Content-Type application/pdf to https://api.aiipworld.com/v1/uploads. The answer contains an upload_id. Each request takes one file.
Next, send a POST to https://api.aiipworld.com/v1/pdf-jobs with JSON that includes op set to pdf_to_text, params, and files set to the upload_id. The params are layout (true or false), pages, page_markers (true or false) and allow_repair. Send your API key with an Authorization: Bearer header or an x-api-key header.
Then poll GET /v1/jobs/:id until the job succeeds, fails or times out. A successful result includes the text file, chars, pages_out and empty. The download_url points to a .txt file and is a short-lived signed link. The result is empty when there is no text layer, and a hint suggests the image_to_text (OCR) operation. Errors include 400 invalid_params, 413 file_too_large, 422 not_a_pdf, 404 upload_not_found, 402 insufficient_credits and 429 rate limited. A failed job can return error codes such as encrypted_pdf, corrupt_pdf, too_many_pages, page_out_of_range and bad_params.
The page shows a ready cURL, Node and Python example, built from the settings you chose. For the general API, see /docs/. There is no batch endpoint and no webhooks yet.
Privacy: what happens to your file
Your file is sent to our server to make the result. Nothing is processed in the browser. You must have the right to use what you upload, as set out in our Acceptable Use Policy.
The uploaded file is used only to make the result. The working copy is deleted as soon as the job ends, whether it succeeds or fails. We keep no history of your jobs. The result is deleted after 10 minutes in the free web tool, and the result panel shows how long it will stay. Download links are short-lived, so save your text when you get it.
Questions
Can I convert a PDF to text for free?
Yes, you can use the free web tool without an account, within the daily limit of 20 jobs per visitor.
How can I copy text from PDF files without selecting it?
The tool lets you copy text from a PDF into a .txt file in one step, so you do not have to select it in a viewer. It copies only stored text, so a scan gives nothing.
How do I copy the text of only some pages?
Enter the pages in the Pages field before you start, such as 1-3,5. Leave the field empty to convert every page.
Why does the tool say no text was found?
The PDF has no text layer, so it is probably a scan or a set of pictures. Use the Image to Text tool to read text from those pages.
Does the tool read scanned PDFs?
No, the tool copies only stored text and does not read pictures of text. For scanned pages, the result panel points you to the Image to Text tool.
What does keeping the layout do?
It lines up the text with spaces so it looks closer to the page. It is a best-effort setting, and it changed little in our test of a simple one-column document.
Will columns and tables come out right?
They may not. Columns and tables can come out uneven, even with the layout option on. We have not tested documents with several columns or many tables, so check the result.
Is the text saved as a .txt file?
Yes. The output is a plain UTF-8 text file, and you can download it as text.txt or copy the text from the box.
Can I extract text from a password-protected PDF?
No, encrypted PDFs are refused, and no password is accepted. The tool does not try to open or break the protection.
Do I pay for a PDF with no text?
No, a PDF with no text costs nothing, and the reserved credit is refunded. A signed-in conversion that returns text costs 1 credit.
Can I convert a PDF to text in my own code?
Yes, the API has the pdf_to_text operation, a way to turn PDF into text from code. Upload the file first, then create a job and poll it until it finishes. The page shows ready cURL, Node and Python examples, and the general API guide is at /docs/.
Need this in your app or in bulk?
This tool runs on the same platform as the API, so the same merge, split or rotate is two HTTP requests from your code: upload each PDF, then start the job. A free account includes 100 credits a month.